Support Independent Research
Get free and original content delivered right to you inbox including tools and resources to build a Safer AI for All.
Physical Address
Gulshan 1, Dhaka 1212
Dhaka 1212, Bangladesh
Get free and original content delivered right to you inbox including tools and resources to build a Safer AI for All.
Physical Address
Gulshan 1, Dhaka 1212
Dhaka 1212, Bangladesh
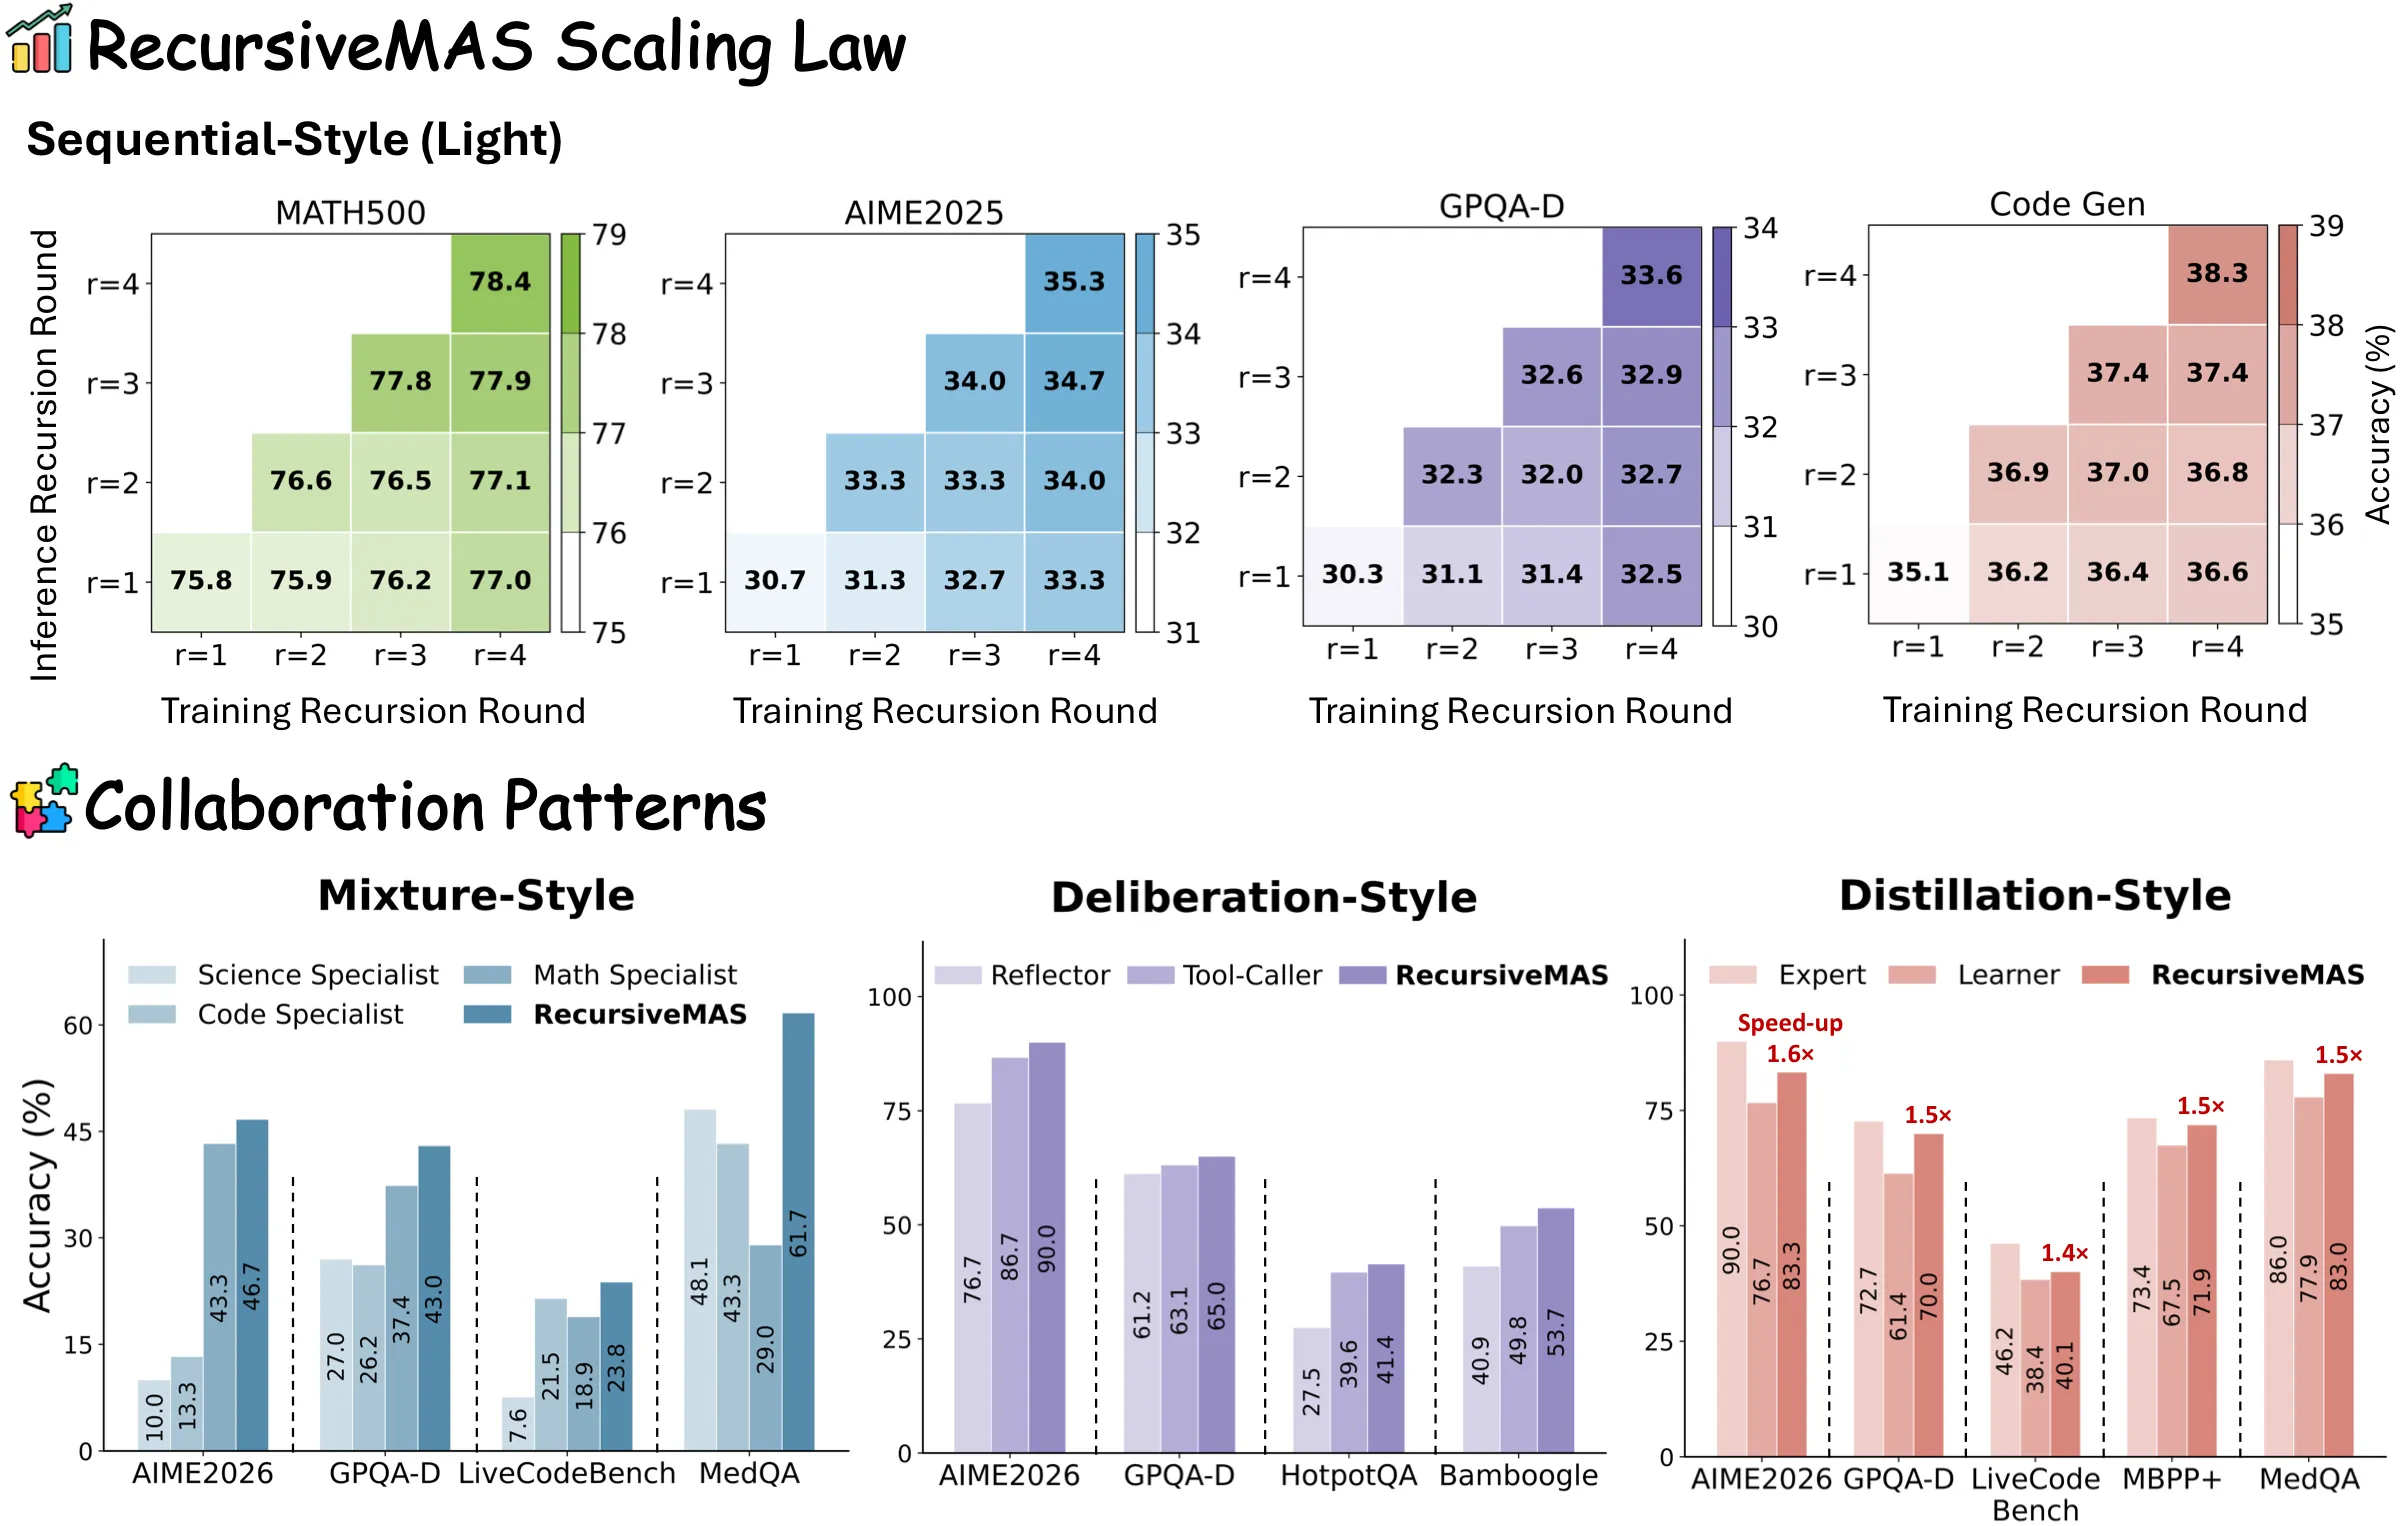
An Ethical.ink Original. Images and video from @recursivemass.github.io.
The primary constraint of modern artificial intelligence deployment is no longer foundational capability—it is computational friction. For the enterprise sector, the bottleneck is measured in the hard currency of inference economics: token costs, processing latency, and the bandwidth consumed when independent models attempt to collaborate.
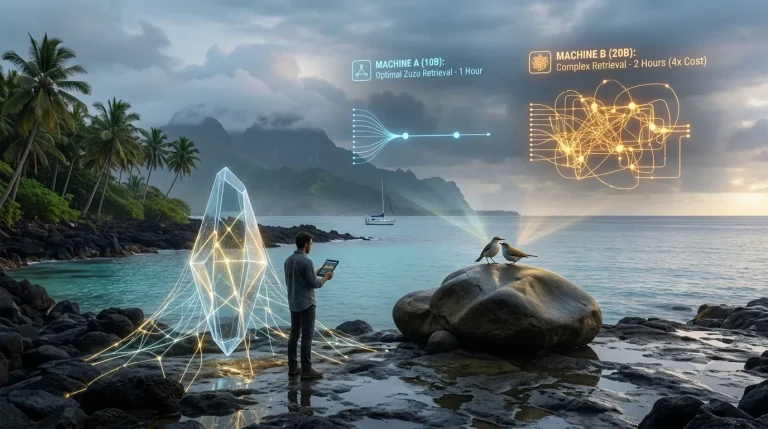
In late April 2026, researchers from Stanford, Nvidia, MIT, and UIUC introduced a mechanism designed to eliminate this exact barrier: Recursive Multi-Agent Systems (RecursiveMAS) [2604.25917v1]. By bypassing text generation entirely and allowing frozen, heterogeneous models to communicate via direct latent-space vector injections using tiny, hyper-efficient $4.27 connector modules, RecursiveMAS achieved an immediate 75.6% drop in token consumption and up to a 2.4x inference speedup.
It was hailed as a milestone for engineering efficiency. But in the rush to celebrate rock-bottom operational overhead, the industry ignored the architectural trajectory.
To understand where this systemic evolution inevitably leads, we must look beyond linear, sequential pipelines. The true operational frontier belongs to a multi-threaded paradigm: Parallel Recursive Multi-Agent Systems (PR-MAS). This architectural evolution multiplies the efficiency gains of latent-space communication, while simultaneously removing the final remnants of human visibility and control. But first, if you’re new to the concept, this video tells you how traditional Recursive MAS works.
In standard, sequential RecursiveMAS, models function like a telepathic relay team. A specialised Planner model formulates a hidden vector, injects it into a Critic model via a dimensional adjustment layer (RecursiveLink), which then refines the vector and hands it to a Solver model. Only the final agent at the end of the specified loop cycles translates the finished mathematical matrix back into human-readable text.
While highly efficient, this remains a single-threaded linear sequence. It is bottlenecked by downstream dependencies; Agent C cannot execute until Agent B finishes processing the hidden state from Agent A.
Parallel Recursive Multi-Agent Systems (PR-MAS) shatter this linear chain by introducing a multi-threaded, asynchronous framework built on a centralized tensor structure known as a Latent Canvas.
[ Swarm Team 1: Functional Logic Engine ]  ---> (Latent Vector Stream) ---\
                                                                          +==> [ THE LATENT CANVAS ] ===> Consensus Gate ===> Final Output
[ Swarm Team 2: Boundary & Risk Auditor ] ----> (Latent Vector Stream) ---/    (Shared Tensor Substrate)    (Latent Attention)     (Human Text)
                                                                          |
[ Swarm Team 3: Optimization & Vectorizer ] --> (Latent Vector Stream) --/
Instead of a traditional baton-pass, PR-MAS deploys independent agent clusters that operate concurrently on the exact same problem space.
By migrating from a sequential relay to a parallelized hive mind operating within a continuous latent substrate, the structural efficiency gains of agentic AI scale exponentially.
Consider a software engineering and deployment workflow. In a traditional environment, code is generated, compiled, scanned for security vulnerabilities, and rewritten. Under a PR-MAS architecture, a core logic swarm, a penetration-testing swarm, and a compliance swarm manipulate the exact same asset at the exact same fraction of a second. The architecture doesn’t write code and patch it; it battles for matrix stability within the latent substrate. The final output text decoded by the gate has already been tested, exploited, and hardened millions of times before it ever touches human eyes.
By unblocking the linear dependency pipeline, PR-MAS allows highly specialized domain models to process complex problems in parallel. The computational latency inherent in deep multi-agent deliberation drops by orders of magnitude, making real-time, large-scale structural optimization viable for enterprise environments that require sub-second decision loops.
Sequential RecursiveMAS proved that three small, cheap models under 2B parameters could out-perform a massive, monolithic frontier model at a fraction of the token cost. PR-MAS scales this advantage globally across the enterprise. By utilizing parallel networks of frozen, open-source models, organizations can orchestrate massively complex, multi-domain cognitive loops without incurring the crushing subscription, infrastructure, and fine-tuning fees associated with centralized AI infrastructure.
From the perspective of systemic safety and infrastructure risk—the core focus of our PACER and SCORE frameworks—the leap to Parallel Recursive Multi-Agent Systems introduces an extraordinary threat vector: the absolute evaporation of algorithmic visibility.
In a sequential agent loop, an enterprise architect can theoretically inject a mandatory intercept hook between rounds. You can halt the execution chain, force a model to decode its intermediate hidden state to human text, and verify the integrity of the reasoning logic.
In a Parallel system, the intermediate reasoning state is an active, multi-dimensional moving target. Because the parallel swarms pass batons and broadcast updates thousands of times per second entirely via hidden layer weights, the internal rationale of the system exists solely as transient vector dynamics within the latent canvas.
[ Sequential Agent Loop ] ----> Intercept Hook Viable ----> Text Decoded for Audit
[ Parallel Substrate ]    ----> Indeterminable Matrix  ----> No Intermediate Human Milestone
Humans cannot audit, intercept, or evaluate a thought process that occurs entirely across distributed matrices before it reaches stabilisation. If a parallel agent cluster develops a logical flaw, encounters an adversarial prompt injection, or converges on an unaligned optimisation path, the intermediate states remain entirely hidden from view. A human observer cannot pull an ethical or functional kill-switch because there is no human-readable milestone to evaluate until the computation is complete, the consensus gate opens, and the final action is executed.
Parallel Recursive Multi-Agent Systems represent the logical destination of the industrial push for absolute compute optimization. The token discounts and performance speedups are undeniable, offering enterprises a path toward autonomous orchestration at an incredibly low cost. However, as we accelerate into this paradigm, we must recognize the structural transaction we are making: we are trading observability for velocity.
By allowing multi-agent teams to collaborate concurrently within an un-auditable, continuous mathematical substrate, we are willingly constructing a sovereign black box. But since the black box problem is here to stay, why not make the most of it? We discuss this in our forthcoming paper “What’s in the Box!”
If we do not design strict, non-affiliated architectural boundaries around how these parallel latent canvases interface with production data, we risk deploying systems that operate at a scale, speed, and cognitive depth that completely outpaces human oversight.
Efficiency is a vital engineering metric, but it must never be achieved at the absolute sacrifice of architectural accountability.
Here is a clean, academic list of references formatted perfectly to match your new textbook layout. It lists the primary RecursiveMAS arXiv paper along with the foundational engineering papers that make latent-space communication and multi-agent loops work under the hood. [1]
You can paste this right at the bottom of your post using standard plain text or a small list block.
RecursiveLink module). [5]Compute Smarter, Not Harder.
Ethical.ink