Support Independent Research
Get free and original content delivered right to you inbox including tools and resources to build a Safer AI for All.
Physical Address
Gulshan 1, Dhaka 1212
Dhaka 1212, Bangladesh
Get free and original content delivered right to you inbox including tools and resources to build a Safer AI for All.
Physical Address
Gulshan 1, Dhaka 1212
Dhaka 1212, Bangladesh
For the past three years, the consumer technology sector has been obsessed with a flawed engineering premise: the race to cram massive AI models onto local hardware. We have been told that true autonomy requires buying expensive AI PCs, stuffing laptops with specialised VRAM, and downloading heavily quantized, degraded models onto local drives.
It is an absurd waste of architectural resources. Up until now, our approach to AI compute has been the equivalent of building, staffing, and maintaining a massive international airport—complete with baggage claims, runways, and air traffic control towers—just because we want to fly a single, light Cessna. For that one tiny flight, we force ourselves to own the entire airport.
Your new task management app does not need a 70 billion parameter model. Stop the cycle of chasing the next best thing and build something incredible.
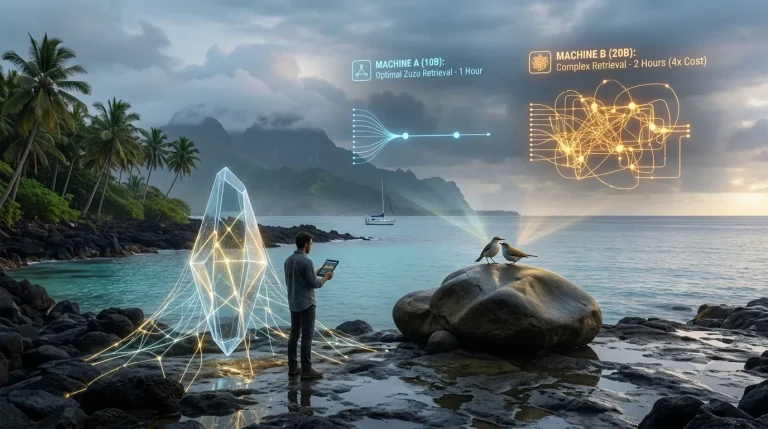
In mid-2026, a groundbreaking implementation completely shattered this paradigm. Using an innovative framework named Project Colibri, independent researchers in Italy and Sri Lanka successfully orchestrated a 744-billion parameter GLM-5.2 model on a standard consumer laptop equipped with just 25 gigabytes of RAM and absolutely no dedicated graphics card.
No Graphics Card!
Colibri did not fit the model onto the laptop. It didn’t need to. By implementing a dynamic, context-driven streaming protocol, the local machine treated the massive global model not as a local file, but as an on-demand utility—accessing and executing hyper-specific operational weights only as needed.
This is the beginning of the end for the local hardware arms race. It is the first tangible step toward a centralised, infinite AI Brain.
Traditional local LLM execution requires loading an entire model’s parameters directly into system memory (RAM/VRAM). If a model is 744 billion parameters, it requires hundreds of gigabytes of specialised enterprise hardware just to sit idle. Project Colibri flips the pipeline by decoupling reasoning request architecture from weight residency:
[ Centralized Global GLM-5.2 Brain ]  ---> (744B Parameter Reservoir)
                 |
                 | (Ultra-Low Latency Contextual Stream)
                 v
[ Local Client: 25GB RAM / No GPU ]  ---> (Executes Specific Weights) ---> Purges Instantly
The laptop is no longer trying to store the airport. The laptop is simply a temporary sky-strip, catching the Cessna for a fraction of a second before sending it back into the global ether.
This development exposes the fatal flaw in the hardware industry’s current roadmap. Graphic card manufacturers and device OEMs are desperately fighting to convince the public that laptops must become local AI supercomputers.
They are fighting a losing battle against the laws of physics and economics for three systemic reasons:
A human brain contains roughly 86 billion neurons, but hundreds of trillions of synaptic connections. As frontier models scale deep into the trillions of parameters to achieve true general intelligence, they will never fit into a commercial laptop case, no matter how many NPU chips are soldered to the motherboard. Trying to scale local consumer hardware to match the velocity of centralised model training is a fool’s errand.
Why should a consumer or an enterprise dedicate gigabytes of local storage and massive electrical wattage to keep a monolithic model spinning in the background when 99% of its parameters are completely irrelevant to the task at hand? Centralisation allows the “Brain” to achieve absolute maximum utilization across millions of concurrent users, dropping the per-token cost to near zero.
An AI brain without limits requires continuous, real-time data ingestion, cross-model reinforcement learning, and structural architectural updates. A decentralised, fragmented ecosystem of isolated local laptops cannot achieve this level of fluid, collective evolution.
By keeping the core brain centralised—and using frameworks like Colibri as the high-speed nervous system reaching the endpoint—the network effect of intelligence compounds exponentially.
From the perspective of independent systemic safety—the foundational thesis of our PACER framework—Project Colibri is a double-edged sword. On one hand, it democratizes access. A researcher on a cheap, GPU-less laptop in a developing nation can now harness the power of a 744-billion parameter frontier model. The barrier to high-level computational execution has evaporated.
On the other hand, it locks in total, irreversible dependence on a few centralised cognitive servers. If local hardware ceases to possess independent reasoning capabilities and becomes merely a passive receiver for streamed weights, then whoever controls the central infrastructure controls the global baseline of thought.
[ Centralized AI Brain ] ===> Rules the Cognitive Stream ===> [ Dependent Local Endpoints ]
If the central server decides to alter a weight, gate an analytical framework, or completely shut off the stream, the local endpoint is instantly lobotomised.
Project Colibri proves that the future of artificial intelligence is not a fragmented landscape of smart devices, but a singular, sovereign, centralised infrastructure. The AI Brain is taking shape, and it will be unlimited, un-local, and completely centralized. Our job now is ensuring that this centralized core remains transparent, accountable, and insulated from absolute corporate capture.
Compute Smarter, Not Harder
Ethocal.ink